
Intelligent Document Processing
Scope a document-to-system workflow with field validation, exception review and an auditable delivery record.
Explore Intelligent Document Processing
Last reviewed August 15, 2026
Pharos Production delivers production AI development services led by PhD engineers - RAG systems, model fine-tuning, MLOps, evaluation gates and drift detection. The team has shipped 25+ AI systems since 2023, taking each from data pipeline and model selection through deployment and ongoing monitoring.
Choose a service to review its scope, delivery options and relevant project evidence.
Scope a document-to-system workflow with field validation, exception review and an auditable delivery record.
Explore Intelligent Document ProcessingCustom AI is purpose-built around your data, evaluation set and quality gates, while off-the-shelf LLM SaaS is a packaged tool with shared prompts and limited control. According to a 2024 a16z enterprise AI survey, 60% of enterprise AI buyers cite data privacy and accuracy as the top reasons to move from SaaS to custom builds. The right choice depends on data sensitivity, accuracy budget and how unique your workflows are.
| Factor | Custom AI build | Off-the-shelf LLM SaaS |
|---|---|---|
| Data control | Your data stays in your VPC or on-prem; full audit trail | Data sent to vendor; subject to vendor retention policy |
| Accuracy | Tuned on your eval set; measurable accuracy uplift over time | Generic accuracy; no eval loop tied to your domain |
| Latency control | Hosted close to your users; sub-200ms achievable | Bound by vendor regions; cold-start spikes possible |
| Cost at scale | Cost decreases with volume (own GPU or batch inference) | Per-token billing scales linearly; no volume discount cliff |
| Integration | Native integration with your data warehouse, ERP, CRM and observability stack | Webhooks/Zapier or vendor SDK; limited deep integration |
| Compliance | HIPAA, GDPR, SOC 2 controls baked in; documented data flows | Vendor BAA/DPA required; some workloads ineligible |
| Time to first value | 6-12 weeks for an MVP with a working evaluation harness | Days for a basic integration; weeks to harden it |
| Lock-in risk | Open weights, portable prompts, swap providers in days | Vendor lock-in on prompts, evals and pricing model |
Diagrams reviewed
Original diagrams Pharos Production uses during discovery to frame AI investment decisions. These are our own working artifacts, not reused marketing graphics. Cite them with attribution.
Three questions that pick the right architecture before you write code.
Illustrative annual TCO curves at 2026 public cloud and GPU prices. Crossover position shifts with model choice, utilization and discounts.
Pick the right customization strategy by task narrowness and data freshness.
The last three years reshaped AI engineering from research experiment to regulated production infrastructure. Prompt engineering on GPT-3.5 became cost-sensitive RAG, then agent orchestration with evaluation harnesses and now a measurable cost crossover where custom AI beats generic SaaS on recurring enterprise workloads. Each shift brought new guardrails, new regulation and a new generation of models. The milestones below are the ones that changed how we scope, price and ship AI at Pharos Production.
Our AI practice ships production systems, not demos. PhD-led research direction, a dedicated MLOps team and 25+ AI systems delivered since 2023 across enterprise search, agent orchestration, fraud detection and clinical decision support. We work the full stack: model selection (open-source vs API), retrieval pipelines (RAG, hybrid search, reranking), fine-tuning when warranted, evaluation sets gated against the NIST AI RMF and drift detection in production. We do not paste OpenAI keys onto static templates and call it AI. Every project ships with an offline eval suite, shadow-mode rollout, hallucination guardrails and an MLOps loop for retraining cadence. We routinely advise clients to NOT use AI when a deterministic rules engine wins on cost and latency, and we say so before quoting. Our production AI work is anonymized under NDA, so its before and after numbers sit in Real client transformations further down this page. Below are delivered platform projects from FinTech, healthcare and other data-heavy clients.


Pharos Production collaborated with a taxi aggregator platform to develop a high-load ride-hailing application that connects passengers and drivers in real time. This platform consolidates various fleets and independent drivers into a single system, ensuring quick ride matching, live tracking and transparent pricing. Built on a cloud-native infrastructure, the solution offers low-latency interactions, reliable trip processing and scalability for operations at the city and regional levels.


Pharos Production has partnered with Sagas to create a location-aware social platform that enables users to capture, publish and explore geo-located timelapses over time. This system combines real-time data ingestion, large-scale media processing and map-centric discovery to transform physical locations into dynamic digital stories. Leveraging cloud-native infrastructure and event-driven architecture, Sagas allows users to document urban changes, natural evolution and personal moments tied to specific places. The result is a scalable social network where time and location are central to content discovery.


Pharos Production has partnered with Pulse to create a community-driven social network that connects users with local stores through challenges, engagement activities and real-world prizes. This platform transforms everyday local interactions into interactive experiences, enabling users to earn rewards from participating merchants. Built on a scalable, event-driven architecture, Pulse facilitates real-time interactions between users and businesses and supports rapid growth across cities and regions.


Pharos Production has partnered with Pleenk to build a secure, scalable payments platform for fast transactions, fraud prevention and seamless integration with digital products. The platform processes payment flows in real time while maintaining high levels of security, transparency and reliability for both businesses and end users. Built on cloud-native infrastructure and an event-driven architecture, Pleenk provides a strong foundation for modern digital payments.


Pharos Production partnered with Nextcheck to replace outdated, manual onboarding with a secure, automated KYC/AML platform. Built on AWS, Kubernetes, Istio, Elixir, RabbitMQ, PostgreSQL and NextJS, the platform provides real-time biometric and document verification, risk assessment and compliance reporting. Since 2019, Nextcheck has reduced onboarding time by 60%, cut manual labor by 70% and expanded to support thousands of checks at once. Today, it powers global banks, FinTechs and crypto firms with a cloud-native, regulation-ready, growth-oriented compliance platform.
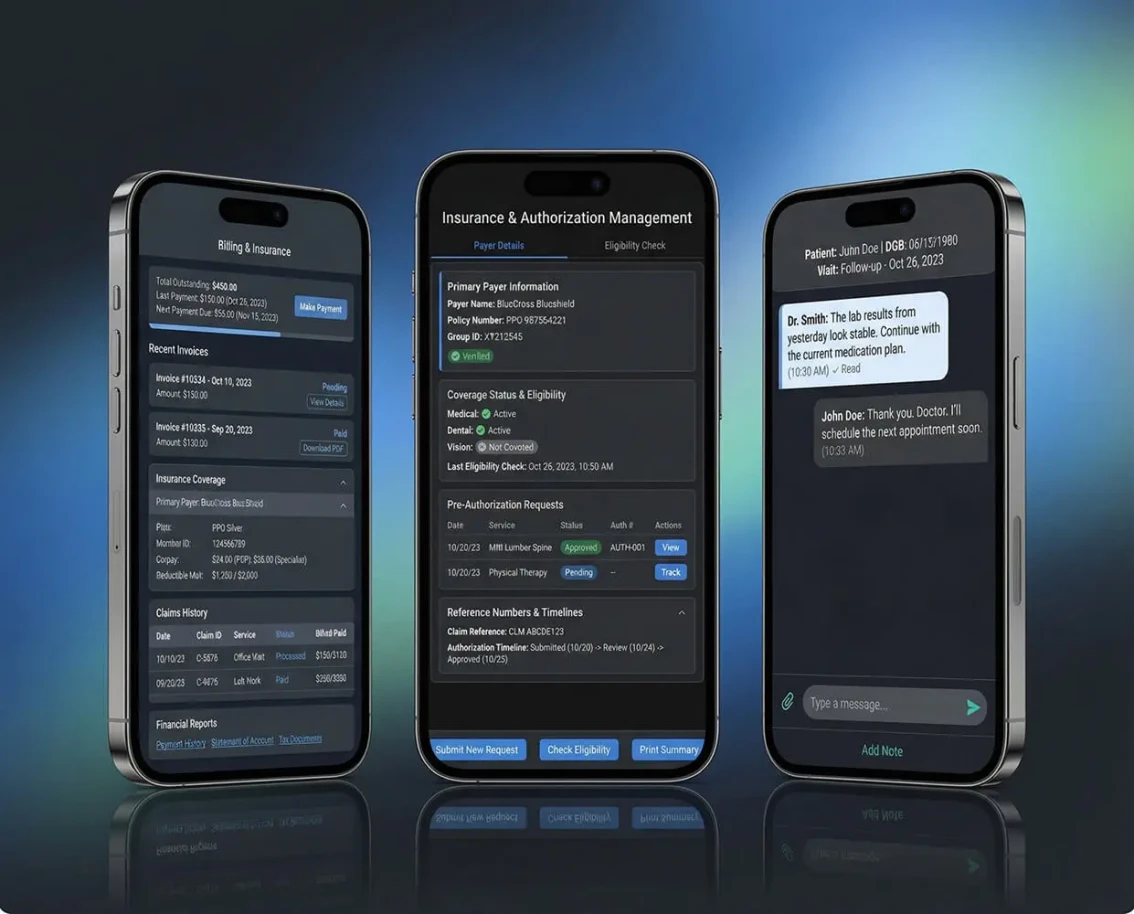
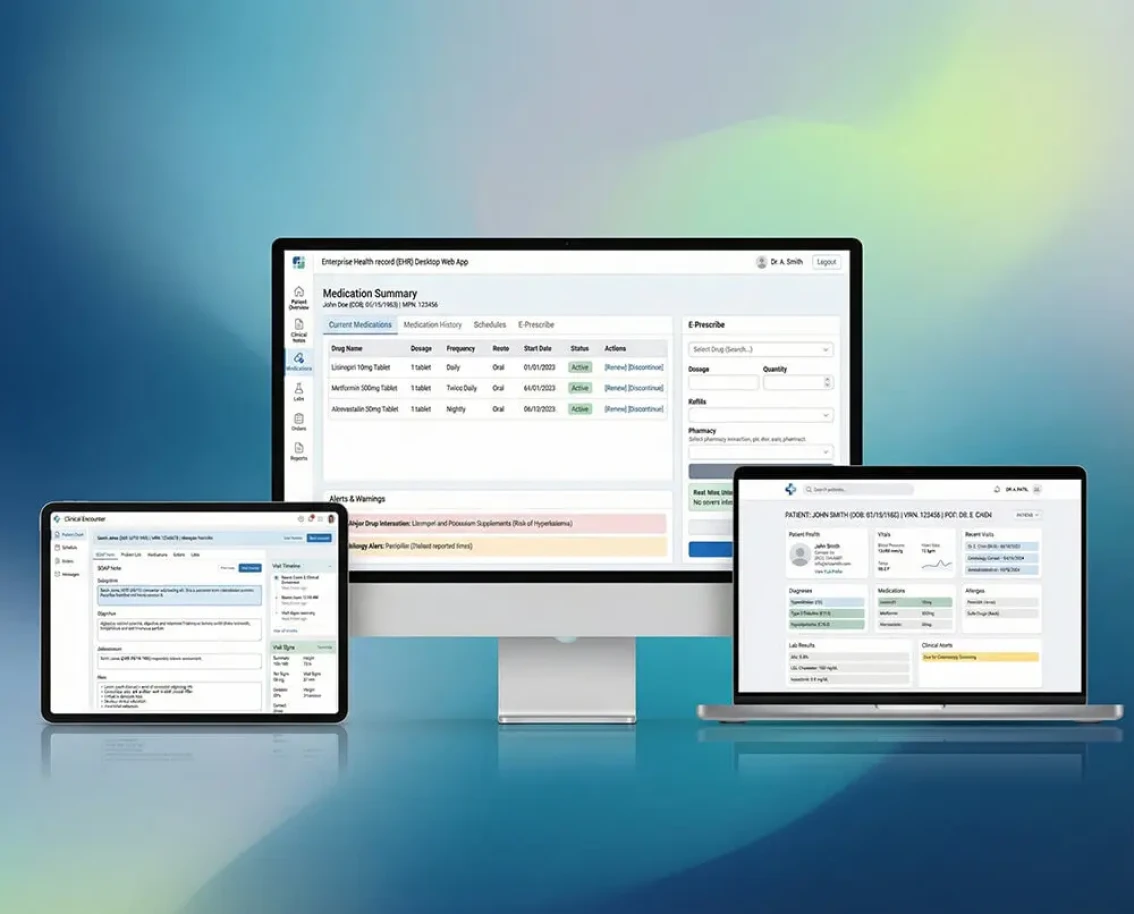
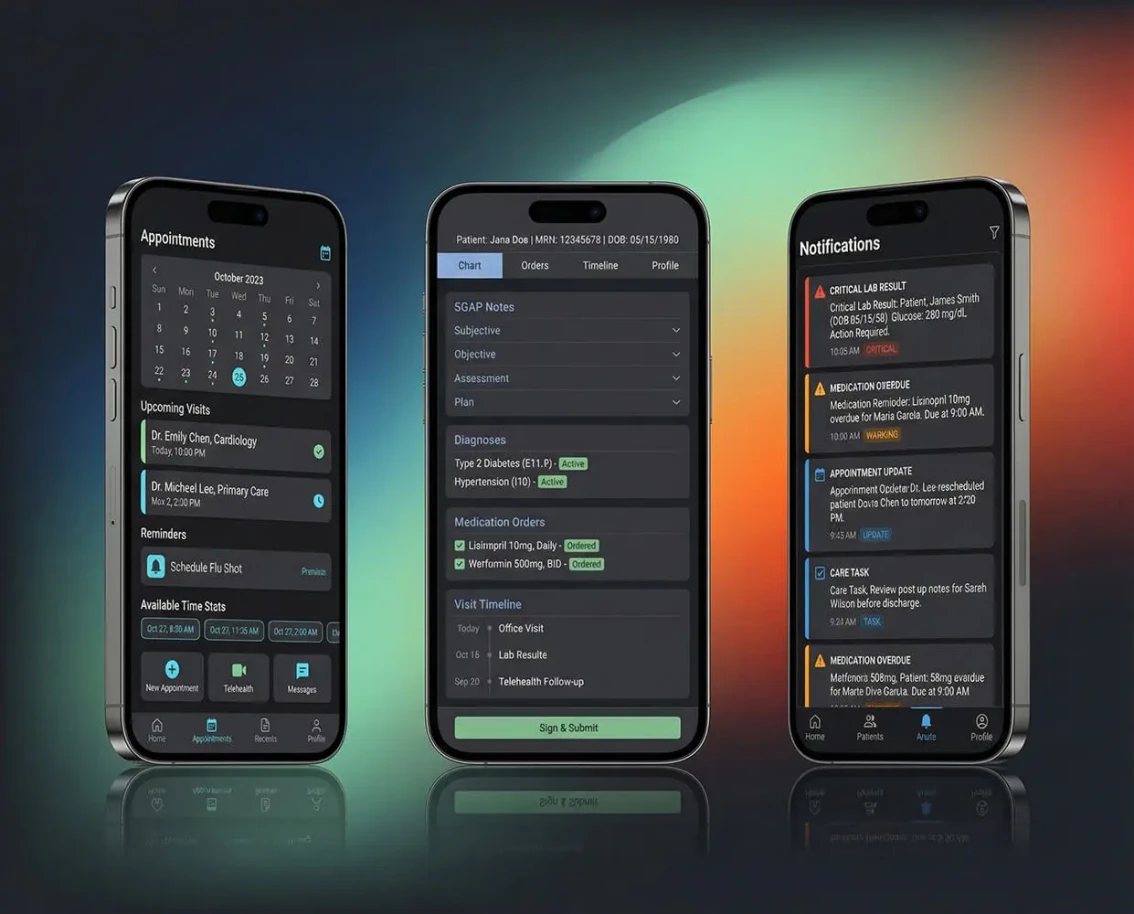
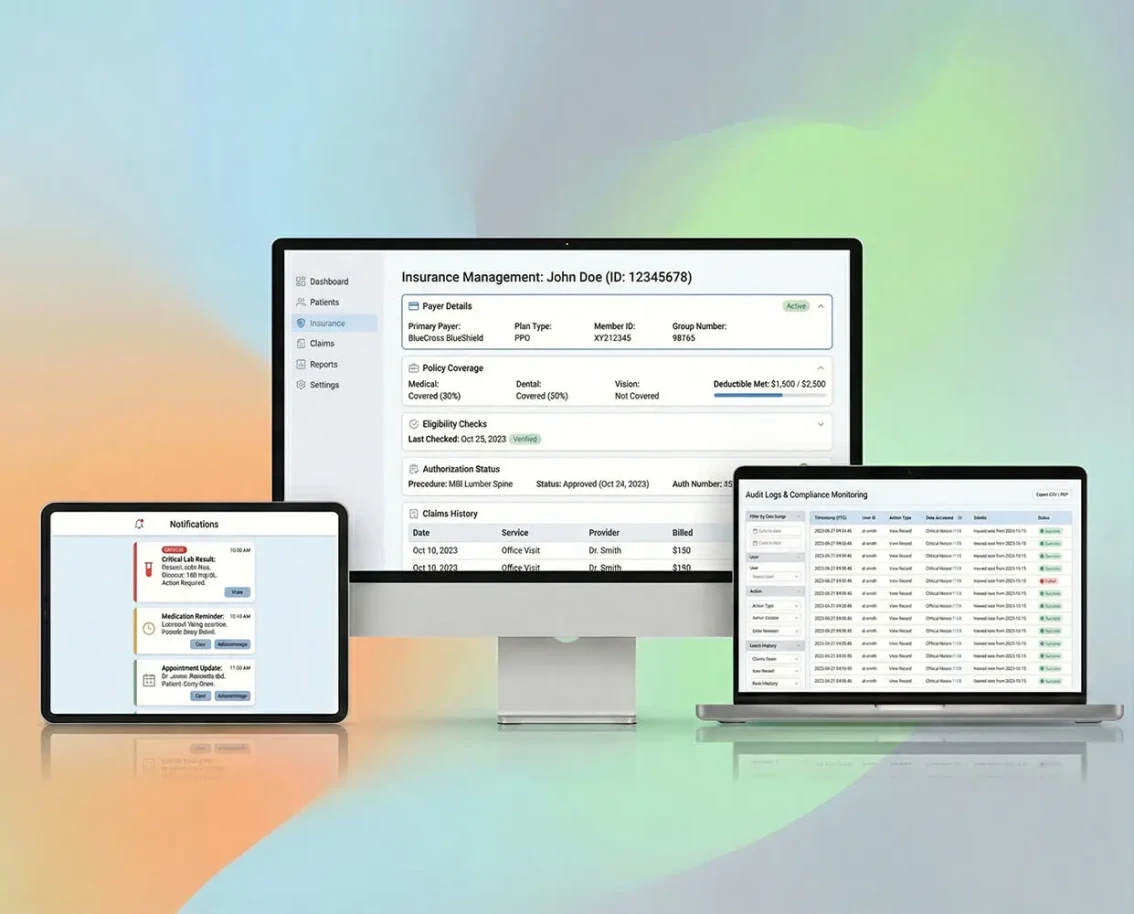
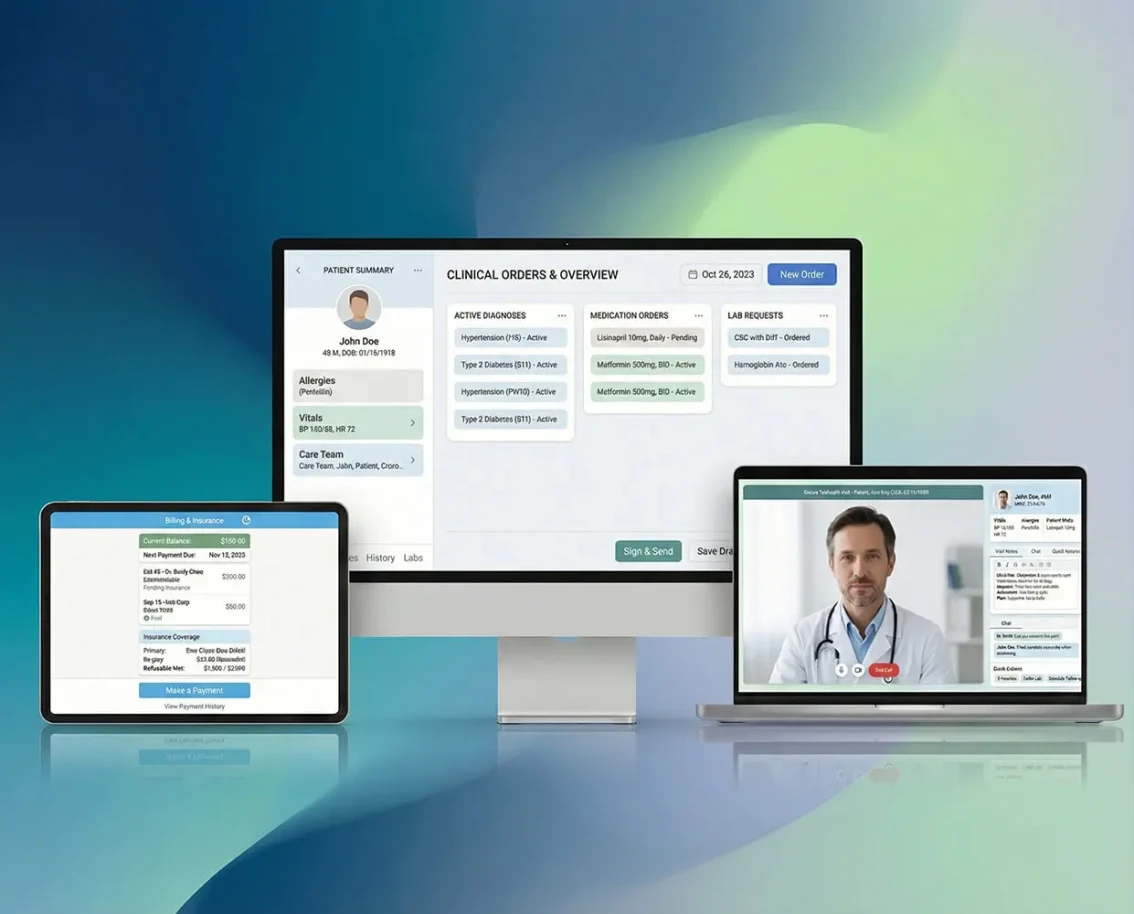
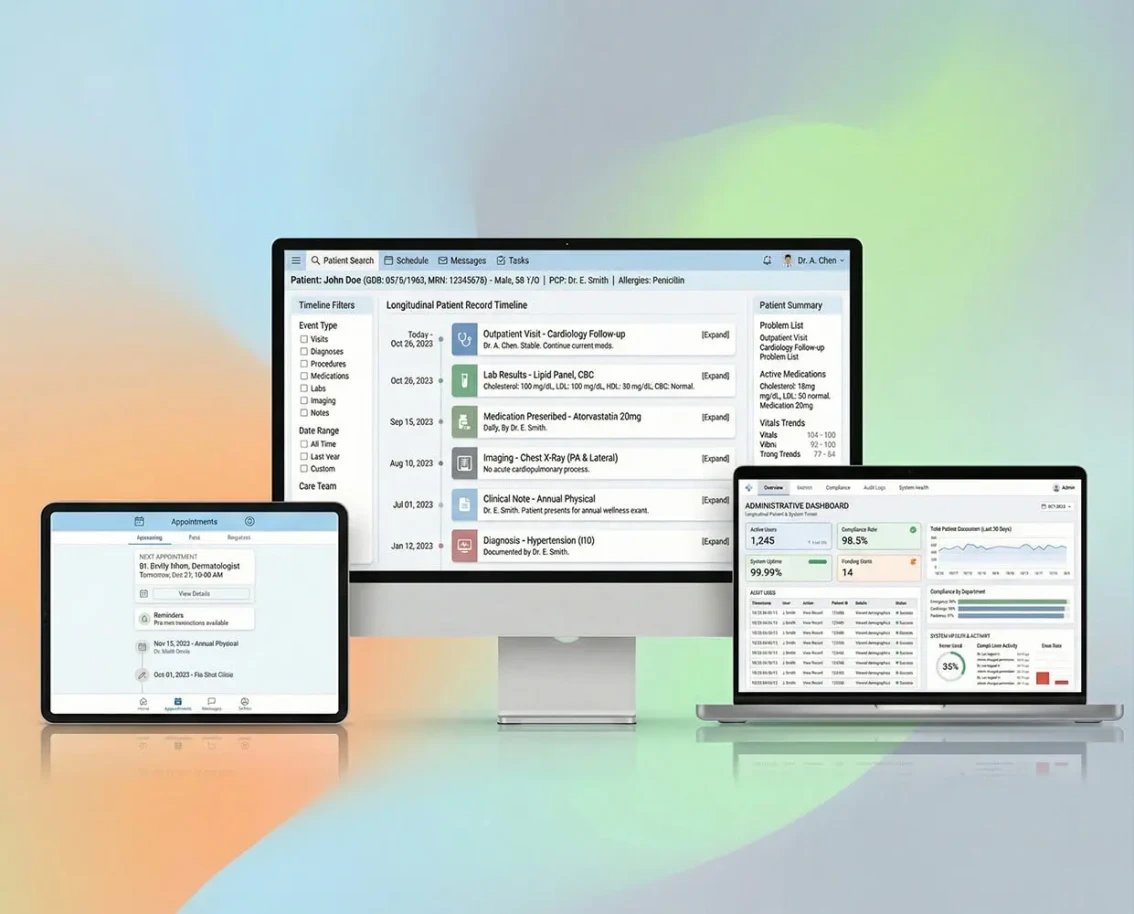
Pharos Production partnered with a healthcare organization to design and build MedCore, a comprehensive electronic health record platform that centralizes patient data, streamlines clinical workflows and ensures regulatory compliance. The system unifies medical records, clinical documentation, diagnostics and administrative processes within a secure, scalable digital environment. Built on a cloud-native architecture, MedCore delivers reliable performance, real-time data access and long-term scalability for healthcare providers operating at clinic, hospital and network levels.
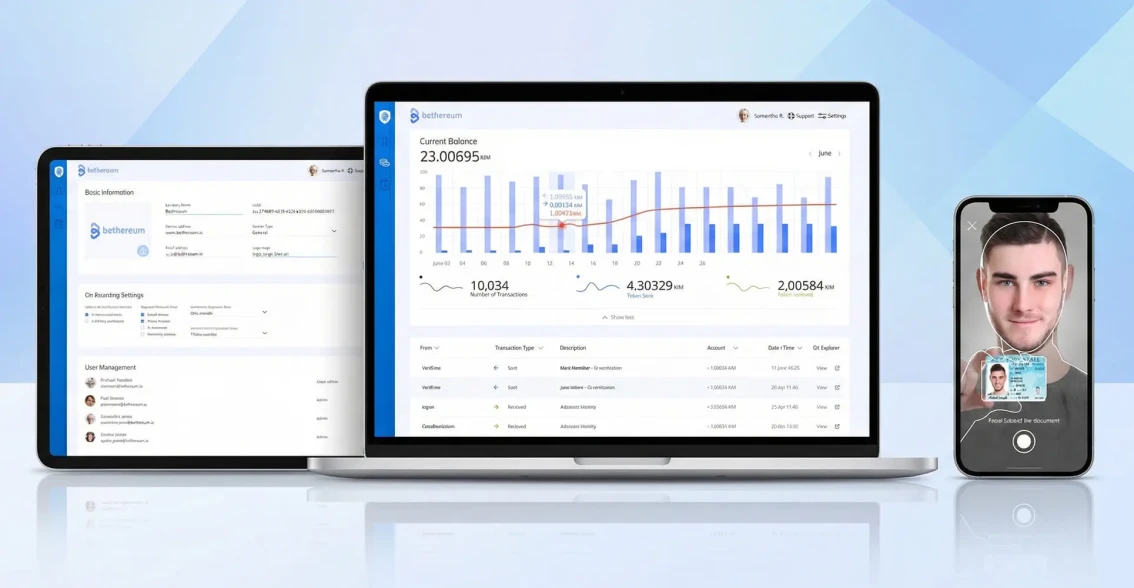
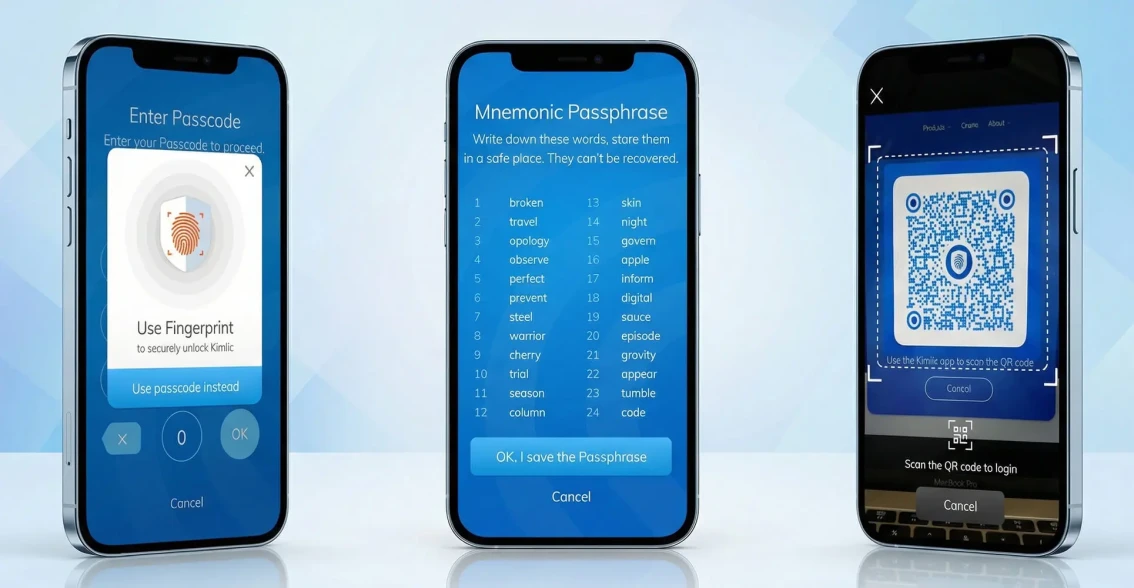
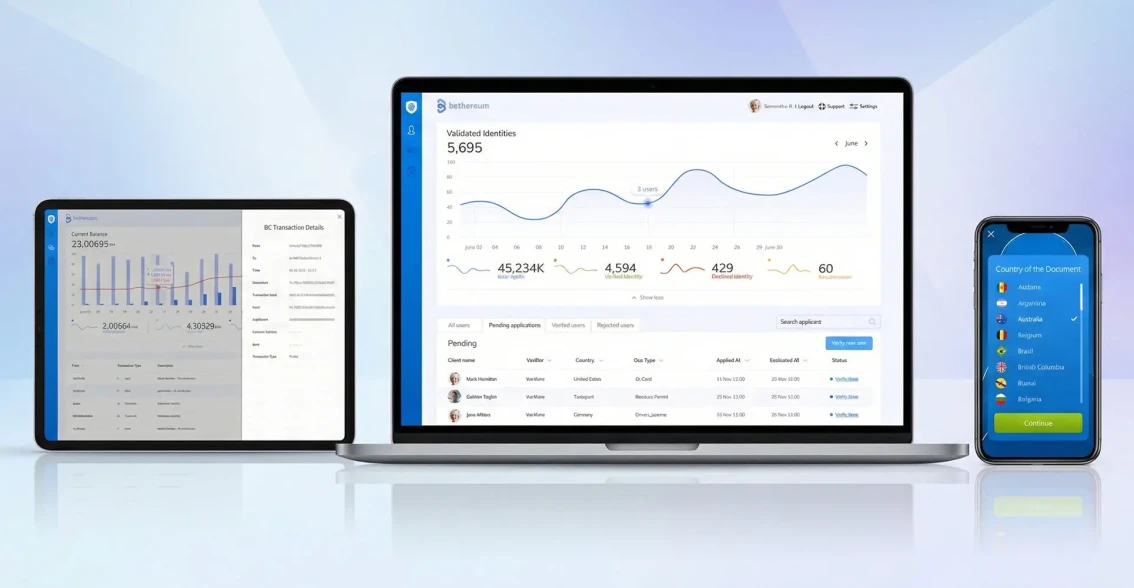
Pharos Production has partnered with Kimlic to develop a blockchain-based Know Your Customer (KYC) and digital identity platform. This platform ensures that user verification is secure, reusable and privacy-preserving across Web3 and FinTech ecosystems. Users can verify their identity once and then securely share proof with multiple services without exposing sensitive personal information. Built on cloud-native infrastructure and equipped with real-time data pipelines, Kimlic provides compliant identity verification at scale while allowing users to retain control over their data.
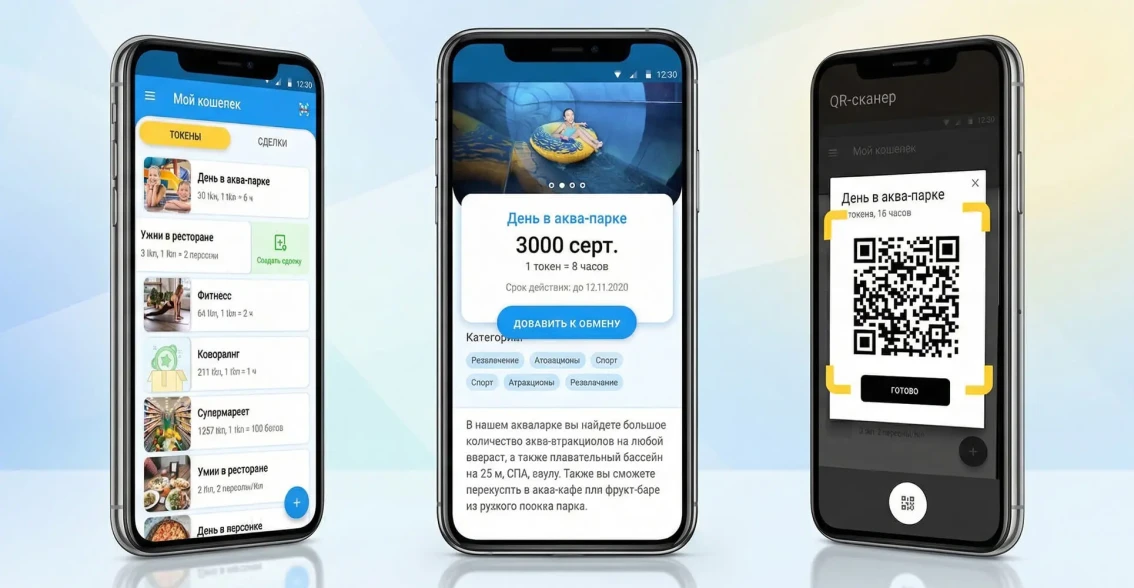
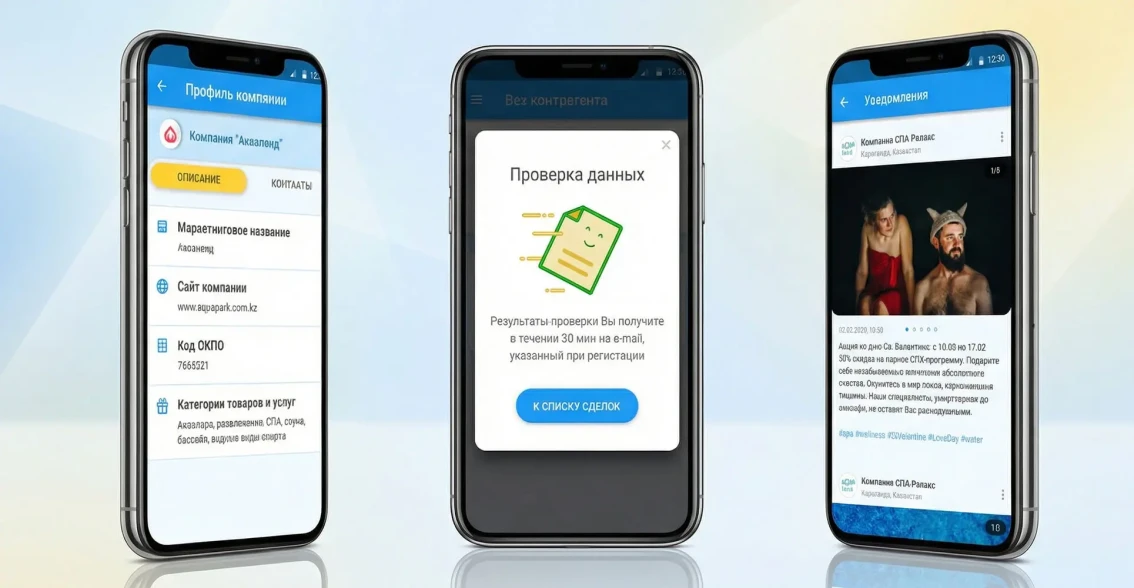
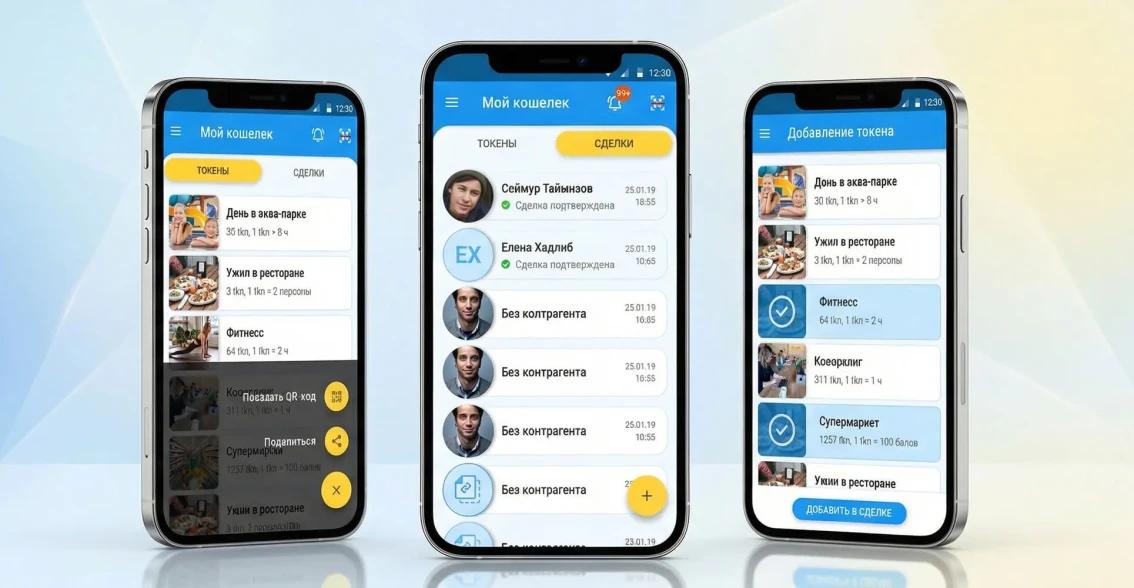
Pharos Production partnered with Dostyq to create a modern loyalty and rewards platform that helps users collect, manage and exchange bonuses, gift certificates and cashback in one place. The app makes reward usage easier by enabling instant and secure transfers and redemptions. Since 2018, Dostyq has become a trusted shopping partner in Kazakhstan, increasing customer engagement and helping retailers strengthen loyalty programs on a large scale.
Founder and CTO Pharos Production
I design and build reliable software solutions - from lightweight apps to high-load distributed systems and blockchain platforms.
PhD in Artificial Intelligence, MSc in Computer Science (with honors), MSc in Electronics & Precision Mechanics.
13 years in architecture of great software solutions tailored to customer needs for startups and enterprises
23 years of practical enterprise customized software production experience
Lecturer at the National Kyiv Polytechnic University
Doctor of Philosophy in Artificial Intelligence
Master's degree in Computer Science, completed with excellence
Master's degree in Electronics and precision mechanics engineering
The Pharos AI Eval Loop is our four-step delivery cycle for production AI: Scope, Build, Eval and Hardening.
maps the use case to an evaluation set drawn from real client data, defines disallowed behaviors and answers the question "can this be solved without AI?" before any code is written
ships the smallest model and retrieval architecture that beats the baseline on the eval set, with prompt versioning under git and reproducible inference
runs shadow-mode comparison against human baselines or rules-engine baselines on live traffic with no user impact, until accuracy, fairness and latency thresholds are met
installs drift detection, output guardrails, audit logging and a documented rollback plan before any production cutover
The loop is named because production AI is never one-shot delivery - we re-enter Eval and Hardening on every prompt change, model upgrade or data shift across the engagement lifetime.
Pharos Verified Delivery applied to 110+ production applications since 2013
Anonymized before/after snapshots from production projects. Metrics measured against client-reported pre-engagement baselines.
12 full-time agents handling 8,000 tickets per week. Average response time 4.2 hours. Tier-1 questions consumed 70% of agent capacity.
Custom AI agent deflects 62% of tier-1 tickets with 91% customer satisfaction. Agents now focus on complex cases. Response time on remaining tickets dropped to 28 minutes.
We started with a 200-question evaluation set built from real ticket history, ran the agent in shadow-mode for 3 weeks against human responses and only routed live traffic once accuracy beat the human baseline on tier-1 categories.
Junior attorneys spent 6-8 hours per case reviewing precedent documents. Inconsistent citations across the team.
RAG system over 50,000 case documents with 3-second response time. Citation precision 94% verified against ground truth. Junior attorney research time cut by 75%.
Built on a private vector store with citation tracking back to source paragraphs. Every answer ships with a verifiable footnote so partners can audit any response in under 30 seconds.
Manual orchestration of 6 internal tools for finance ops. 14-day month-end close. Three full-time analysts.
Multi-agent system with finance specialist, data extractor, validator and reporter. Month-end close in 3 days with full audit trail. Analysts redeployed to higher-value forecasting work.
Each agent has a narrow tool surface and a structured handoff protocol. Every action is logged with the full prompt, intermediate state and final tool call, so finance can replay and audit any close-cycle step on demand.
Client names anonymized under NDA. Full case studies at /cases/.
Of inbound requests asking for AI, roughly 30% have received a different recommendation since 2023, most often because a deterministic rules engine fits the problem better and costs less. Here is how we think about scope:
Every AI engagement begins with "can this be solved without AI?" If yes, we say so and recommend the cheaper path.
Original research based on 25+ Pharos AI projects: cost ranges by complexity tier, hidden costs analysis, ROI timelines and team composition.
Independent reviews from Clutch, GoodFirms and direct client testimonials - verified feedback on our software projects
Based on 342 verified reviews
Trusted by Coinbase, Consensys, Core Scientific, MicroStrategy, Gate.io and 10+ more Web3 and enterprise platforms
16+ partnersOur 16 technology partners include:
Recognized on Clutch, GoodFirms and The Manifest for software engineering excellence

65+ industry awards
Practice led by Dmytro Nasyrov
Founder and CTO
23+ years in custom software development. Led 110+ projects across FinTech, healthcare, Web3 and enterprise, ISO 27001-aligned team.
Technically reviewed by Victor Sineglazov, D.Sc.
Independent AI Scientific Advisor
Professor, Artificial Intelligence Department, Igor Sikorsky Kyiv Polytechnic Institute. Head of the Aviation Computer-Integrated Complexes Department, Kyiv Aviation Institute.
Reviewed for technical accuracy on August 15, 2026. Not an endorsement of any commercial claim on this page.
Pharos Production scopes engagements in three tiers, AI discovery and PoC, Production AI system and Enterprise AI platform, with typical budgets from $15,000 to $500,000+ depending on scope and complexity.
Feasibility study, prototype on your data and integration roadmap in four to eight weeks.
Full model development, API layer, cloud deployment and MLOps with monitoring.
Multi-model architecture, custom data infrastructure, compliance and hybrid or on-prem delivery.
Prices vary based on project scope, complexity, timeline and requirements. Hourly rates range from $50 to $99 depending on role and seniority. Contact us for a personalized estimate.
Need extra hands on your software project? Our developers can jump in at any stage - from architecture to auditing - and integrate seamlessly with your team to fill any technical gaps.
Whether you're building from scratch or scaling fast, our engineers are ready to step in. You stay in control, and we handle the code.
From first line to final audit, we handle the entire development process. We will deliver secure, production-ready software, while you can focus on your business.
| Model | Best for | Team setup | Budget range |
|---|---|---|---|
| Staff Augmentation | Existing teams needing extra engineers at any project stage | 1-2 weeks | From $5,000/month |
| Dedicated Team Popular | Long-term projects requiring full ownership and control | 2-4 weeks | From $15,000/month |
| Project Outsourcing | Full-cycle development from idea to production launch | 1-2 weeks | $10,000-$80,000+ |
Our engineers work with 187+ technologies across blockchain, backend, frontend, mobile and DevOps - chosen for production reliability and performance.
Our engineers work with 187+ technologies across 10 categories: Frameworks, AI, Blockchains, DevOps, Clouds, Databases, Brokers, Tests, Programming, UI/UX.

Our company starts and assembles an entire project specialists with the perfect blend of skills and experience to start the work.
We'll design, build and launch your MVP, ensuring it meets the core requirements of your software solution.
We'll create a complete software solution that is custom-made to meet your exact specifications.
Our company will be right there with you, keeping your software solution running smoothly, fixing issues and rolling out updates.
Original research based on 25+ Pharos Production AI projects delivered 2023-2026. Cost breakdowns by complexity tier, hidden costs analysis, team composition, ROI timelines and regional variation. Key finding: median AI MVP cost is $42,000 but hidden costs add 28-42% to first-year totals.
Enterprise AI adoption in 2026 is at a tipping point. 78% of enterprises report using AI in at least one business function, but only 22% have successfully scaled AI beyond pilot projects, according to the McKinsey Global AI Survey (2024). The gap between experimentation and production deployment is where most AI initiatives fail - not […]
How much does AI development cost in 2026? AI development costs range from $10,000 for simple chatbots to $500,000+ for enterprise multi-agent systems. The final cost depends on four factors: model complexity, data preparation needs, integration scope and ongoing inference costs. AI development cost by project type Simple AI features like FAQ chatbots and basic […]
Multi-agent systems represent a fundamental shift in how enterprises build AI. Instead of relying on a single monolithic model to handle every task, multi-agent architectures deploy specialized AI agents that collaborate, delegate and coordinate to solve complex business problems. This guide covers the architecture patterns, frameworks, coordination strategies and production deployment lessons that engineering teams […]
Practical guide to implementing machine learning for business in 2026. Covers ML use cases across industries, ROI frameworks, implementation steps, cost analysis and common pitfalls with specific numbers and benchmarks.
AI agent vs LLM explained: an LLM generates text, while an AI agent wraps an LLM with tools, memory and a control loop to take actions and complete multi-step tasks.
Enterprise NLP applications guide covering contract analysis, sentiment analysis, chatbots and document processing. Implementation strategies, cost benchmarks and ROI data for 2026.
AI automation in 2026 has moved far beyond chatbots and simple workflow triggers. Enterprises are deploying autonomous AI agents that plan, reason and execute multi-step business processes with minimal human oversight. This article covers the most consequential AI automation trends shaping enterprise operations - from agentic process automation and AI-native software development to autonomous supply […]
Quick Comparison: LangChain vs CrewAI vs AutoGen Factor LangChain/LangGraph CrewAI AutoGen Best for Production systems, complex state Role-based teams, rapid prototyping Code generation, research tasks Learning curve Steep (large API surface) Moderate (role-based abstraction) Moderate (conversation patterns) Production readiness High (LangSmith observability) Medium (growing ecosystem) Low (research-oriented) Multi-agent LangGraph for orchestration Built-in role assignment Conversation-based […]
Type to filter questions and answers. Use Topic to narrow the list.
Showing all 10
No matches
Try a different keyword, change the topic or clear filters
A production-ready RAG system typically takes 8-12 weeks: 2 weeks discovery and evaluation set creation, 4-6 weeks build (ingestion pipeline, embeddings, retrieval, generation, eval harness), 2-4 weeks production hardening (drift detection, monitoring, rollback). Pharos uses a shadow-mode evaluation phase where the RAG system runs alongside human baselines before going live.
The agent service lists planning ranges of $60,000-$120,000 for a pilot, $240,000-$680,000 for a production multi-agent system and $510,000-$1,600,000 for an enterprise platform. These scopes differ in tool integrations, evaluation, permissions, monitoring and handover. Discovery produces the estimate for your workflow. Model usage, hosting and ongoing support are separate operating costs. See AI agent development for the scope and our AI cost research for cost drivers.
Start with prompt engineering. Move to RAG when you need the model to use your private data or when answers must be grounded in citations. Fine-tune only when (a) the task is narrow and high-volume, (b) you have 1,000+ labeled examples, (c) prompt and RAG approaches plateau on your eval set. Parameter-efficient fine-tuning with LoRA and QLoRA cuts trainable parameter count by two to three orders of magnitude, which makes the training step affordable but does not eliminate the serving, evaluation and on-call costs. In practice, 80% of Pharos AI projects ship without fine-tuning. Fine-tuning makes sense for domain-specific tone, structured output reliability and inference cost reduction at scale.
Hallucinations are mitigated through layered controls: grounded retrieval (RAG with citation tracking), structured output schemas with validation, confidence thresholds with human handoff, an evaluation set tested on every deploy and runtime guardrails that flag low-confidence answers. We also instrument every response so you can audit any answer back to its source documents.
Use cloud LLM APIs (OpenAI, Anthropic, Vertex) when latency is not extreme, data residency rules allow it and your usage is below ~1B tokens/month. Self-host open-source models (Llama, Mistral, Qwen) when you have hard data residency requirements, need sub-200ms latency on long context or your monthly token spend would justify GPU infrastructure. Epoch AI inference cost trends show the crossover point moves every 6 to 12 months as hosted-API prices fall and open-weight models get more efficient. We help model the cost crossover point during discovery.
Every Pharos AI project includes: a documented use case with intended and disallowed behaviors, an evaluation set covering accuracy, fairness and safety, content filtering for harmful outputs, audit logging of every prompt and response, drift monitoring with alerts and a rollback plan. Controls map to NIST AI RMF, EU AI Act risk categories and the OWASP Top 10 for LLM Applications. For regulated industries we add bias testing, explainability layers and human-in-the-loop checkpoints on consequential decisions.
We baseline before/after metrics during discovery. For customer support automation: ticket deflection rate, CSAT, agent capacity freed.
For document Q&A: research time per task, citation precision. For multi-agent ops: cycle time, error rate, headcount redeployed. Pharos requires a measurable business metric in every AI engagement - if we cannot define it, we will not start the project.
Yes. Pharos AI engineers integrate with existing data warehouses (Snowflake, BigQuery, Redshift), feature stores (Feast, Tecton), MLOps platforms (Vertex, SageMaker, Databricks) and observability (Arize, WhyLabs, Datadog).
We avoid creating parallel infrastructure and prefer to add AI capabilities to your existing data plane.
For roughly 30% of inbound requests asking for AI, we recommend a different stack instead. Common reasons: business rules are deterministic and a rules engine is 100x cheaper; the use case requires zero-error guarantees on individual predictions; sub-100ms latency budgets that LLM inference cannot meet; no plan for ongoing prompt maintenance or drift monitoring; data residency rules out cloud LLM APIs without budget for self-hosted GPUs.
Frameworks: LangChain, LlamaIndex, Haystack, DSPy. Model providers: OpenAI, Anthropic Claude, Google Vertex, AWS Bedrock, self-hosted Llama and Mistral.
ML toolkits: PyTorch, TensorFlow, Hugging Face Transformers. Vector stores: Pinecone, Weaviate, pgvector, Qdrant. The right stack depends on your latency budget, data residency rules and existing infrastructure.
External authorities, standards bodies and primary documentation referenced throughout this AI guide.
Published record
Technical articles, comparison guides and methodology deep-dives we write from our own delivery experience.
Achieve them with minimized risk through our bespoke innovation capabilities
Contact us today to discuss your project. We're ready to review your request promptly and guide you on the best next steps for collaboration
Same dayWe're committed to keeping your information confidential, so we'll sign a Non-Disclosure Agreement
1 dayAfter we chat about your goals and needs, we'll craft a comprehensive proposal detailing the project scope, team, timeline and budget
3-5 daysLet's connect on Google Meet to go through the proposal and confirm all the details together!
1-2 daysAs soon as the contract is signed, our dedicated team will jump into action on your project!
Same dayHeadquarters in Las Vegas, Nevada. Engineering office in Kyiv, Ukraine.
We also work with clients through dedicated local teams in Las Vegas, New York and San Francisco.
Thanks for the request!
We typically reply within 24 hours