Pharos Production collaborated with a taxi aggregator platform to develop a high-load ride-hailing application that connects passengers and drivers in real time. This platform consolidates various fleets and independent drivers into a single system, ensuring quick ride matching, live tracking and transparent pricing. Built on a cloud-native infrastructure, the solution offers low-latency interactions, reliable trip processing and scalability for operations at the city and regional levels.
Last reviewed August 15, 2026
AI Integration Services
Pharos Production delivers AI Integration services that connect artificial intelligence capabilities to your existing business systems without replacing them.
- 25+ AI projects delivered
- 90+ engineers
- 108 Clutch reviews
282 published client reviews across 3 platforms. Counts are summed; reviewers may appear in more than one source.
Profiles checked . Glassdoor: 46 employee reviews, 5.0/5, reported separately.
Case Study
See the products we built and the engineering work involved. Each case describes its scope and delivery context.
-
-
Pharos Production has partnered with Sagas to create a location-aware social platform that enables users to capture, publish and explore geo-located timelapses over time. This system combines real-time data ingestion, large-scale media processing and map-centric discovery to transform physical locations into dynamic digital stories. Leveraging cloud-native infrastructure and event-driven architecture, Sagas allows users to document urban changes, natural evolution and personal moments tied to specific places. The result is a scalable social network where time and location are central to content discovery.
-
Pharos Production has partnered with Pulse to create a community-driven social network that connects users with local stores through challenges, engagement activities and real-world prizes. This platform transforms everyday local interactions into interactive experiences, enabling users to earn rewards from participating merchants. Built on a scalable, event-driven architecture, Pulse facilitates real-time interactions between users and businesses and supports rapid growth across cities and regions.
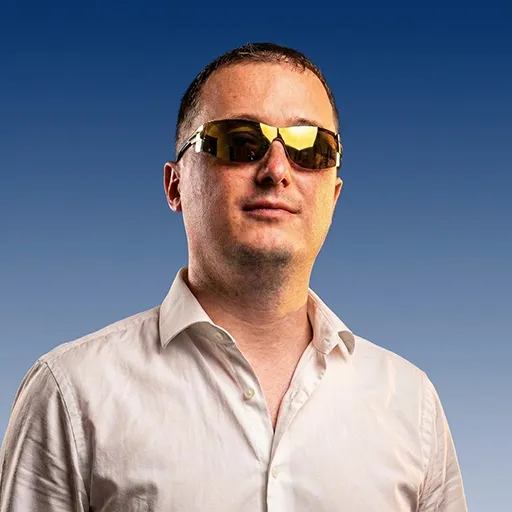
Practice led by Dmytro Nasyrov
Founder and CTO
23+ years in custom software development. Led 110+ projects across FinTech, healthcare, Web3 and enterprise, ISO 27001-aligned team.
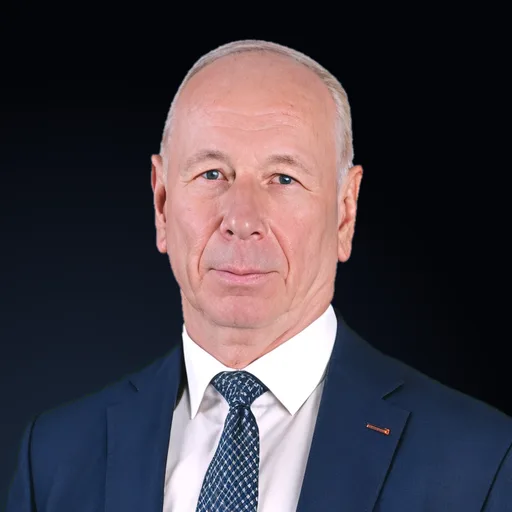
Technically reviewed by Victor Sineglazov, D.Sc.
Independent AI Scientific Advisor
Professor, Artificial Intelligence Department, Igor Sikorsky Kyiv Polytechnic Institute. Head of the Aviation Computer-Integrated Complexes Department, Kyiv Aviation Institute.
Reviewed for technical accuracy on August 15, 2026. Not an endorsement of any commercial claim on this page.
What is AI integration?
Authoritative citations 12 sources
-
Stanford AI Index
The Stanford AI Index tracks multi-year movement on ML benchmarks, training compute, responsible AI metrics and enterprise adoption across industries, making it the most cited yearly reference for grounding ML investment cases.
hai.stanford.edu
-
Papers With Code
Papers With Code maintains live state-of-the-art leaderboards for ML tasks across image classification, object detection, NLP and tabular prediction, which we use to pick baselines before committing to a model family.
paperswithcode.com
-
arXiv, Chen and Guestrin 2016
The XGBoost paper by Chen and Guestrin remains the most cited gradient boosting reference and underpins tabular ML baselines we still ship in FinTech and logistics systems a decade after publication.
arxiv.org
-
NeurIPS 2017, LightGBM
Ke et al. introduce Gradient-based One-Side Sampling (GOSS) and Exclusive Feature Bundling (EFB) in LightGBM. Their experiments compare efficiency on the datasets in the paper; production performance depends on the workload.
proceedings.neurips.cc 2017
-
McKinsey State of AI
McKinsey documents annual enterprise ML adoption across functions like marketing, service operations and supply chain, and consistently reports that scaled ML correlates with higher EBIT contribution versus pilot-only organizations.
mckinsey.com
-
Gartner AI Hype Cycle
Gartner maps enterprise ML techniques across the hype cycle phases, flagging which capabilities are production-ready for mid-market adoption versus still speculative, which we cross-check before recommending a build path.
gartner.com
-
IDC Worldwide AI Spending Guide
IDC publishes the worldwide AI spending guide with multi-year forecasts by industry, use case and geography, which we reference when sizing three-year total cost of ownership for ML platform engagements.
idc.com
-
NIST AI Risk Management Framework
The NIST AI RMF defines a govern, map, measure and manage lifecycle for AI systems that we apply to production ML including model cards, bias testing and incident response procedures for regulated deployments.
nist.gov
-
OWASP ML Security Top 10
OWASP maintains a ranked list of the top machine learning security risks including input manipulation, training data poisoning, model theft and adversarial attacks, which we use as a threat model checklist before exposing any ML endpoint.
owasp.org
-
O'Reilly AI Adoption in the Enterprise
The O'Reilly AI adoption survey tracks ML maturity stages across enterprises, reporting on deployment percentages, skills gaps and the most common production blockers which consistently include data quality and monitoring rather than model choice.
oreilly.com 2022
-
Google Cloud MLOps Architecture
Google Research published the canonical MLOps continuous delivery reference describing three maturity levels from manual to fully automated pipelines, which we use as the template for client MLOps roadmaps and capability gap assessments.
cloud.google.com
-
PyTorch Blog
The PyTorch engineering blog tracks the 2.x production tooling surface including torch.compile, TorchServe updates and quantization workflows, which shape our default serving stack for sub-50ms p99 inference on GPU and CPU targets.
pytorch.org
- Training foundation models from scratch (we do not do that)
- Stand-alone research projects with no product target
- Integrations that bypass the client's existing auth, audit and logging stacks
- One-off batch scripts marketed as AI features
- Generative surfaces with no evaluation set or rollback plan
AI integration at a glance
- Production integrations: 60+ AI integrations shipped since 2022 across SaaS, marketplaces, FinTech and content platforms
- Default stack: OpenAI or Anthropic SDKs directly, plus lightweight orchestration. We avoid heavy frameworks when a 40-line module will do.
- Integration pattern: Always reversible: feature flag, cost ceiling, eval set, rollback path in the first release
- Latency budget: Typical target 300-800 ms P95 for user-facing integrations; batch surfaces have different budgets
- Pricing: Integration projects from $35,000; ongoing eval and monitoring from $6,500/month
- Observability: Cost per request, eval pass rate, drift warning and rollback event all wired to the client's existing observability stack
- Exit ramp: Every integration has a documented rollback path and a kill-switch flag
AI integration vs custom model build
| Factor | AI integration | Custom model build |
|---|---|---|
| Lead time | 4-10 weeks | 4-9 months |
| Cost | $35K-$180K one-time | $180K-$900K plus ongoing ML ops |
| Infra owned | Foundation model vendor owns model | You own weights and inference stack |
| Evaluation | Prompt + retrieval eval sets | Full train/validation/test discipline |
| When it fits | Most product features; speed to market | Core moat, regulatory constraints or latency <50 ms |
How we ship AI into existing products
Pharos Verified Delivery applied to AI integration means the integration ships with a rollback lever, a cost ceiling, an evaluation set and an alert threshold from the first production call.
-
Phase 01 / 04 Paid Discovery
Week 0
2-4 weeks
- Technical validation
- Architecture proposal
- Scope refined estimate
82% on-schedule with discovery
-
Phase 02 / 04 Iterative Build
Week 2-4
2-week sprints
- Working demos every sprint
- CTO review at milestones
- ADRs documented
Transparent progress tracking
-
Phase 03 / 04 Production Readiness
Week 8-24
- Monitoring and alerting
- Security audit Pen test
- Runbooks and rollback
ISO 27001 aligned
-
Phase 04 / 04 Support
Launch day
Ongoing
In progress
- Security patches
- Performance tuning
- 4h SLA response
Continuous improvement
Pharos Verified Delivery applied to 110+ production applications since 2013
AI integrations in production
Every integration below has been running in production for at least one quarter. None of them required the client to rebuild their core product.
Support ticket classification (Q3 2024)
22 support tiers manually assigned by front-line agents; median routing time 4 minutes per ticket.
Integrated a classification model behind the existing ticket intake endpoint with human override retained. Median routing time dropped to 38 seconds, accuracy 94%.
The model was the easy part. The integration work was threading the result through the existing auth, audit logging and fallback paths without changing the agent UI.
Semantic search overlay (Q1 2025)
Keyword search missing 41% of user queries per search log analysis.
Added a semantic search layer on top of the existing Elasticsearch index, with graceful fallback. Search success rate went from 59% to 88% without any migration.
We kept Elasticsearch. Replacing a working search engine was scope creep disguised as modernization.
Content moderation augmentation (Q2 2025)
Manual moderation queue with 6 hour SLA and a growing backlog.
Integrated a vision+text moderation model into the listing pipeline with human review for edge cases. Queue SLA dropped to 11 minutes, false positive rate under 1.5%.
The integration kept the human moderator in the loop for anything the model was not confident about. AI moderation that removes the human is where trust fails.
Client names anonymized under NDA. Full case studies at /cases/.
When AI integration is the wrong answer
Some AI feature requests are really UX, data-quality or process problems wearing an AI mask. We tell clients when integration will not help:
- The workflow has a clear deterministic rule and a rule engine would be cheaper and more auditable
- The underlying data is so noisy that no integration can surface anything useful
- The feature is being built to look innovative to a board, not to solve a user problem
- Latency budget is under 50 ms and foundation models cannot meet it
- There is no plan for evaluation, drift detection or rollback
If the problem is really data quality, fix the data pipeline first. If it is UX, redesign the flow. If it is a compliance workflow, use a rules engine. Integration should be the last step, not the first.
Pharos AI integration portfolio
Pharos AI integration delivery portfolio observations, 2022-2026
Ranges we consistently see across 20+ AI integration engagements.
-
0.5-3.2% of production AI calls hit fallback paths on healthy integrations. Above 5% signals upstream degradation or capacity issues.
-
4-10 weeks for standard AI integration into existing app; 10-18 weeks for multi-provider routing with retrieval augmentation and tenant isolation[5].
-
$1.8k-$22k per month in AI API spend for mid-market B2B SaaS, excluding vector store and model hosting[7].
-
Weekly quality checks catch 80-90% of model-version or prompt-template regressions; remainder caught by user feedback within 7 days.
-
Prompt changes ship in 30-90 minutes behind a feature flag; model route changes in 2-4 hours after per-route eval parity check passes[12].
AI integration outlook 2026-2027
Three shifts are reshaping how AI integrates into existing enterprise systems.
-
AI becomes integration layer, not standalone product
Enterprise AI budget shifts from greenfield AI products to augmenting existing CRM, ERP and analytics stacks[5]. Buyers expect AI as a feature not a separate vendor.
-
Model governance moves to security and risk teams
CISOs and risk teams take ownership of model approval, usage policy and incident response. Model inventory, provenance and approval workflow become enterprise risk artifacts[8].
-
AI bill of materials becomes procurement gate
Buyers demand disclosed model provenance, training-data attestation and evaluation evidence. Vendors without AI BOM face stalled procurement[6].
Our four-dimension AI integration evaluation template
Every AI integration we ship runs against the same four-dimension readiness evaluation before handover.
-
30%
Integration reliability
Fallback paths, retry semantics, circuit breakers, P95 latency
Every AI call path has explicit fallback; circuit breakers trip on error rate above 5%; P95 latency measured per integration route[11].
-
25%
Model quality and drift
Quality eval cadence, drift detection, retraining triggers
Quality checks weekly on a domain-specific golden set[1]; drift detected on both input and output distributions; retraining triggers documented per model.
-
25%
Security and privacy
PII redaction, prompt injection resistance, data leakage prevention
PII redacted before model call; prompt injection eval on 30-item adversarial set[9]; no training on client PII without explicit contractual permission.
-
20%
Observability and cost
Per-request logging, cost attribution, usage analytics
Request and response logged with correlation IDs; cost attributed per tenant and feature; usage dashboards for engineering and finance[7].
Production post-mortem
When an embedding model version change broke everyone
A vector-search-driven support tool used OpenAI text-embedding-ada-002 at index time in early 2024. When the team swapped to text-embedding-3-small at query time in October 2025 without re-indexing, cosine similarities collapsed to near-random. Relevance dropped 60 percentage points before we caught the pattern 11 days later; users blamed it on the AI getting dumber in feedback tickets.
Model version pinned per integration path. Embedding re-index workflow documented and rehearsed. Integration test suite now includes version-mismatch detection on every deploy.
Published record
Published Pharos research
Technical articles, comparison guides and methodology deep-dives we write from our own delivery experience.
- State of AI Development Costs 2026
- AI Agent Frameworks Comparison 2026
- Build vs Buy AI Agent: 2026 Decision Framework
- RAG vs Fine-Tuning: When to Use Each Approach
- How to Choose an AI Development Company
- State of Smart Contract Audits 2026
- State of Production AI Engineering 2026
- State of FinTech Compliance Cost 2026
- State of Custom Software TCO 2026
- State of AppSec 2026
- State of Tech Due Diligence 2026
- State of QA and Software Testing 2026
- State of DevOps and Cloud 2026
- How to Choose a Blockchain Development Company
- How to Choose a FinTech Development Company
- FinTech Compliance Checklist 2026: PCI DSS, SOC 2, GDPR and Beyond
- AI in FinTech: Transforming Financial Services in 2026
- Software Development Cost Guide: What to Expect in 2026
- How to Choose a Software Development Company in 2026
- Cybersecurity Essentials for Startups and SMBs in 2026
- FinTech Trends 2026: How Top FinTech Trends are Shaping Digital Banking
Platforms we work with
Technology platforms and company references shown for identification. A logo does not establish a commercial partnership or endorsement.
16 references-
Consensys
-
Gate.io
-
Coinbase
-
Ludo
-
Core Scientific
-
Debut Infotech
-
Axoni
-
Alchemy
-
StarkWare
-
MARA Holdings
-
MicroStrategy
-
Nubank
-
OKX
-
Uniswap
-
Riot
-
LeewayHertz
About the founder and CTO
Founder and CTO Pharos Production
I design and build reliable software solutions - from lightweight apps to high-load distributed systems and blockchain platforms.
PhD in Artificial Intelligence, MSc in Computer Science (with honors), MSc in Electronics & Precision Mechanics.
-
13 years in architecture of great software solutions tailored to customer needs for startups and enterprises
-
23 years of practical enterprise customized software production experience
-
Lecturer at the National Kyiv Polytechnic University
-
Doctor of Philosophy in Artificial Intelligence
-
Master's degree in Computer Science, completed with excellence
-
Master's degree in Electronics and precision mechanics engineering
Choose your project scope
Pharos Production scopes engagements in three tiers, AI discovery and PoC, Production AI system and Enterprise AI platform, with typical budgets from $15,000 to $500,000+ depending on scope and complexity.
AI discovery and PoC
Feasibility study, prototype on your data and integration roadmap in four to eight weeks.
Production AI system
Full model development, API layer, cloud deployment and MLOps with monitoring.
Enterprise AI platform
Multi-model architecture, custom data infrastructure, compliance and hybrid or on-prem delivery.
Prices vary based on project scope, complexity, timeline and requirements. Hourly rates range from $50 to $99 depending on role and seniority. Contact us for a personalized estimate.
Interaction models for staff augmentation, dedicated teams and outsourcing
Request staff augmentation
Need extra hands on your software project? Our developers can jump in at any stage - from architecture to auditing - and integrate seamlessly with your team to fill any technical gaps.
Hire dedicated experts
Whether you're building from scratch or scaling fast, our engineers are ready to step in. You stay in control, and we handle the code.
Outsource your project
From first line to final audit, we handle the entire development process. We will deliver secure, production-ready software, while you can focus on your business.
Technologies, tools and frameworks we use
We select the stack for your product, integrations and operating requirements.
AI and Machine Learning
LLM Providers 8
AI Frameworks 15
Vector Databases 7
MLOps and Infrastructure 11
AI Agent Tools 4
Partnerships and awards
Selected badges from Clutch, GoodFirms and The Manifest. Open the issuer profiles to review categories and dates.
An approach to the development cycle
-
Team Assembly
Our company starts and assembles an entire project specialists with the perfect blend of skills and experience to start the work.
-
MVP
We'll design, build and launch your MVP, ensuring it meets the core requirements of your software solution.
-
Production
We'll create a complete software solution that is custom-made to meet your exact specifications.
-
Continuous Support
Our company will be right there with you, keeping your software solution running smoothly, fixing issues and rolling out updates.
AI integration insights
AI integration key terms 6
- API Gateway
- A managed service or custom layer that sits between client applications and AI model endpoints, handling request routing, authentication, rate limiting, payload transformation and observability.
- Semantic Caching
- A cost-reduction technique that stores AI model responses keyed by embedding similarity rather than exact input match, returning cached results for semantically equivalent queries to cut redundant inference calls.
- Fallback Routing
- An integration pattern that automatically directs AI inference requests to a secondary model provider or degraded-mode response when the primary provider is unavailable, over budget or returning errors above a threshold.
- Prompt Registry
- A version-controlled repository of prompt templates with associated evaluation benchmarks, enabling teams to track changes, run regression tests and roll back prompts that cause accuracy regressions.
- Token Budget
- A per-request or per-session cap on the number of tokens consumed in an AI API call, used to control inference cost and prevent runaway consumption from malformed or adversarial inputs.
- Open-Source LLM
- A large language model with publicly available weights - examples include Mistral, Llama and Falcon - that can be self-hosted in a private environment, eliminating third-party data transfer and providing full control over model updates.
Frequently asked questions about AI Integration Services
Type to filter questions and answers. Use Topic to narrow the list.
Showing all 9
No matches
Try a different keyword, change the topic or clear filters
-
What systems can AI models be integrated with?
AI models can be integrated with CRM platforms (Salesforce, HubSpot), ERP systems (SAP, Oracle, Microsoft Dynamics), customer support tools (Zendesk, Freshdesk), data warehouses (Snowflake, BigQuery) and internal APIs. Integration is built on an API gateway layer that normalizes payloads, manages authentication and routes requests to the appropriate model endpoint.
-
How do you choose between OpenAI GPT, Anthropic Claude, Google Gemini and open-source models?
Model selection is driven by four factors: task type (long-context analysis, coding, multimodal input), latency requirements, cost per token at your expected volume and data residency constraints. Pharos benchmarks candidate models on your actual data and workloads before committing to a primary model and designs fallback routing so a secondary model activates if the primary is unavailable or over budget.
-
What is prompt management and why does it matter at scale?
Prompt management covers versioning, testing and deploying prompt templates as first-class engineering artifacts - stored in a registry, evaluated with regression tests and rolled back if accuracy drops. At scale, unmanaged prompt drift is a leading cause of silent accuracy degradation; a prompt registry enforces review gates before production changes go live.
-
How is AI integration cost controlled in production?
Cost optimization layers include semantic caching (returning stored responses for near-duplicate inputs), token budget enforcement per request type, model tiering (routing simpler tasks to cheaper models), batching asynchronous jobs and usage dashboards with per-team or per-feature cost attribution. These measures typically reduce inference spend by 30 to 60 percent versus naive pass-through integration.
-
How long does an AI integration project typically take?
A single-system integration connecting one AI model to one application - for example GPT-4o into a Salesforce org via a custom API adapter - takes 4 to 8 weeks including prompt design, error handling, testing and go-live. Multi-system integrations with data warehouse connectors, streaming pipelines and governance controls typically run 12 to 20 weeks.
-
What security measures apply to data sent to third-party model APIs?
Before any data leaves your environment, PII detection layers identify and redact sensitive fields. API calls use short-lived credentials rotated via secrets management (AWS Secrets Manager, HashiCorp Vault).
Contractual data processing agreements are reviewed and signed with each provider. For highest-sensitivity workloads, on-premises or private-cloud-hosted open-source models eliminate third-party data transfer entirely.
-
What happens when a model API goes down or returns degraded responses?
Pharos integration architecture includes fallback routing logic that detects provider outages or elevated error rates and switches to a secondary model endpoint automatically. Circuit breakers prevent cascading failures, and dead-letter queues hold failed inference requests for retry or manual review. SLA monitoring dashboards surface availability and latency metrics per model provider.
-
Do you use a heavy framework like LangChain?
Not by default. We use provider SDKs directly and write small orchestration modules.
Heavy frameworks add dependencies and break more often than the simpler path. If a project genuinely needs graph-based agent orchestration, we will use it. Otherwise no.
-
Do you handle compliance and audit requirements?
Yes. Requests and responses can be logged to an audit store, with redaction for PII and selective retention.
We have delivered integrations in insurance, banking-adjacent and regulated health workflows.
The Pharos takeaway on AI integration
AI integration rewards teams that treat model calls as external dependencies with fallback, governance and observability not magic functions[8]. Fallback reliability, drift detection and cost attribution are the three areas that separate AI integrations that survive production from integrations that fail quietly.
Book a 30-minute AI integration readiness call
Your business results matter
Achieve them with minimized risk through our bespoke innovation capabilities
What happens next?
-
Contact us
Contact us today to discuss your project. We're ready to review your request promptly and guide you on the best next steps for collaboration
Same day -
NDA
We're committed to keeping your information confidential, so we'll sign a Non-Disclosure Agreement
1 day -
Plan the Goals
After we chat about your goals and needs, we'll craft a comprehensive proposal detailing the project scope, team, timeline and budget
3-5 days -
Finalize the Details
Let's connect on Google Meet to go through the proposal and confirm all the details together!
1-2 days -
Sign the Contract
As soon as the contract is signed, our dedicated team will jump into action on your project!
Same day